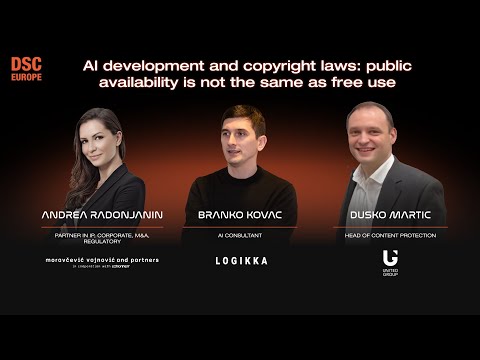
AI Development and Copyright: Public ≠ Free Use
summary
Panel argues that public data is not free: training on scraped YouTube or web content carries copyright risk, and models trained without clear licences can become unmarketable in the EU because the AI Act forces compliance. Examples: Autodesk due diligence on Wonder Dynamics reveals buyers demand dataset audits; litigation cited includes NYT v OpenAI, Getty v Stability, music industry suits, and German Keska v Lion ruling (limits TDM exemptions). Practical fixes urged: provenance logs, explicit licences or collective schemes, and transparency on what data a model actually trains on.
AI-written summary · about
chapters (9)
- 0:00AI and copyright panel intro
- 5:35IP law challenges in AI training
- 11:40Developers' data access obstacles
- 16:39Fair use court cases for AI training
- 24:26AI company compliance checks
- 28:36Innovation vs legal risks in AI
- 35:42Global AI copyright legislation
- 44:37Future AI lawsuits and regulations
- 49:14Closing remarks and Q&A
related talks
 28mAI – Legal Insights
 38mContributing AI-Generated Content to OSS Projects - Navigating Legal, Copyright, &...
 01h 01mLegal and Compliance Insights on Open Source AI in Automotive
 15mEthical and Legal AI Compliance in the Age of FOSS
 53mAI: Law, Policy and Common Sense Suggestions on How to Stay Out of Trouble
 32mGenerative AI & Intellectual Property Law
 17mAI Law & Ethics: developing responsible AI systems
 31mUsing Generative AI to Develop Open Source Code - Practical Guidance for Managing Lega...