Unleash All Cores: Asymmetry-Aware Scalable DNN Inference on Mobile CPUs
Talkat 20th USENIX Symposium on Operating Systems Design and Implementation (OSDI '26) · 2026-07-13..07-15·
summary
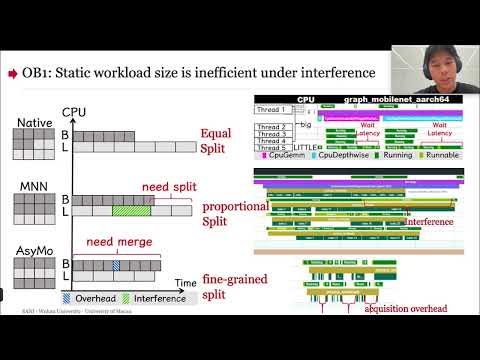
SANI implements an AMP-aware runtime atop Arm-CL that targets mobile CPUs and demonstrates concrete gains: it prepares cluster-specific kernels, dynamically merges or splits workloads, and remaps kernels on migration to preserve affinity. Evaluation on five mobile SoCs and six models shows latency drops of 17.6%–23.7% on average (up to 29.5%) and energy savings up to 39% versus baselines, with online overhead below 3 ms and <2 MB extra memory. affinity-aware kernel issuer adaptive granularity scheduler on-demand kernel switcher
AI-written summary · about
chapters (19)
- 0:00Introduction
- 1:24Low latency for on-device AI
- 2:06CPUs vs GPUs/NPUs for lightweight models
- 2:49Inference pipeline on mobile CPUs
- 4:14Limitations of scheduling
- 5:40Adding cores slows inference
- 6:44Sunny's key observations
- 7:26Sunny's three mechanisms
- 8:29Unifying kernel and workload coordination
- 8:50Affinity-aware kernel selection
- 9:31Adaptive workload granularity
- 10:55Workload migration between cores
- 11:59Index remapping for kernel affinity
- 12:40Experimental results
- 13:45Scalability with heterogeneous cores
- 14:29Energy efficiency improvements
- 14:52Ablation study of Sunny
- 15:32Scope and limitations
- 16:15Conclusion and future
related talks
 16mAccelerating Web AI on
 22mCentimani: Enabling Fast AI Accelerator Selection for DNN Training with a Novel...
 42mAI and Machine Learning BoF
 19mOptimizing CNN Model Inference on CPUs
 38mNEURAL NETWORKS ON YOUR MOBILE PHONE. DIVING INTO THE NN API
 01h 02mMulti-Dimension Mapping of Embedded Applications
 12mAccelerating On-Device ML Inference With ExecuTorch and Arm SME2
 12mCustomizing RISC-V Cores to Accelerate Neural Networks