Build reliable data lakes with Delta Lake & Databricks

summary
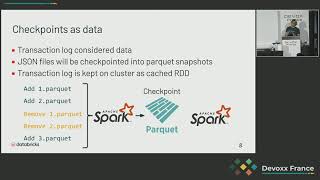
Delta Lake on Databricks adds ACID transactions and schema enforcement to Parquet files on S3 by keeping a transaction log of JSON actions and Parquet data files, enabling serializable writes, optimistic concurrency, and time travel version reads. It supports Spark streaming and batch, MERGE INTO for CDC and deletes, and checkpointing plus VACUUM for retention. Users report ~4,000 orgs and 2+ exabytes processed, data skipping that drops ~97% of files for some queries, and a Comcast case that cuts cluster count and cost by 10x.
AI-written summary · about
chapters (26)
- 0:00Intro
- 0:15What is a data lake
- 1:43Data lake architectures
- 5:44Data lake problems
- 6:55Delta Lake
- 8:46Data quality vocabulary
- 16:12Use case Comcast
- 18:12Getting started with Delta
- 18:58Declarative pipelines
- 20:14Schema management
- 22:38How Delta works
- 24:17Transaction Log
- 25:27Atomicity
- 26:33Consistency Isolation
- 27:22Optimistic Concurrency Control
- 28:52Metadata
- 30:43Delta Website
- 31:05Databricks Booth
- 35:52Comparing old and new platforms
- 39:25Databricks
- 41:07Other features
- 42:35Airflow
- 43:25Delta Table Operations
- 46:22Batching Streaming
- 48:37How to contact Databricks
- 50:16Time travel
related talks
 39mDelta Lake: Diving into Data Lakes Without the Downsides
 31mDelta Lake: Open Source Reliability and Quality for Data Lakes
 28mLakehouse Architecture with Delta Lake and Databricks
 45mSimplify your ETL with Databricks Delta Lake
 20mDelta Lake: Turn your Data Lake into a Lakehouse
 30mDelta Lake and Delta Sharing
 38mGetting Started with Delta Lake
 21mBuilding Data Integration Services In Real Time