Delta Lake: Open Source Reliability and Quality for Data Lakes

summary
Delta Lake is an open source Parquet storage layer that adds ACID transactions and scalable metadata so Spark can safely mix streaming and batch on the same tables. It runs on S3/Azure/HDFS, exposes Spark APIs, and supports update/delete/merge and schema evolution. Production usage already processes 2+ exabytes per month and a Comcast case collapses ten cluster jobs into one and cuts machines by 10x. The project joins the Linux Foundation and aims for broad engine support.
AI-written summary · about
chapters (12)
- 0:00Introduction to Delta Lake
- 1:44Problems with data lakes
- 6:54Introducing Delta Lake solution
- 8:40Bronze silver gold data patterns
- 10:46Streaming vs batch processing
- 12:31Batch job challenges
- 13:54Real-world Delta Lake use cases
- 15:19Getting started with Delta Lake
- 16:02Delta pipelines and expectations
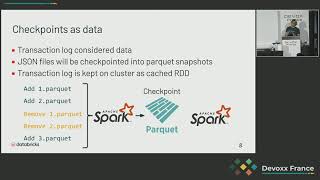
- 19:12How Delta Lake works under the hood
- 24:54Delta Lake roadmap and future
- 25:42Q&A session
related talks
 19mOpen Source Reliability for Data Lakes
 39mDelta Lake: Diving into Data Lakes Without the Downsides
 58mBuild reliable data lakes with Delta Lake & Databricks
 20mDelta Lake: Turn your Data Lake into a Lakehouse
 30mDelta Lake and Delta Sharing
 18mDelta Lake – The Foundation Of Your Lakehouse
 38mGetting Started with Delta Lake
 28mLakehouse Architecture with Delta Lake and Databricks