Text similiarity with the next generation of word embeddings in Gensim
summary
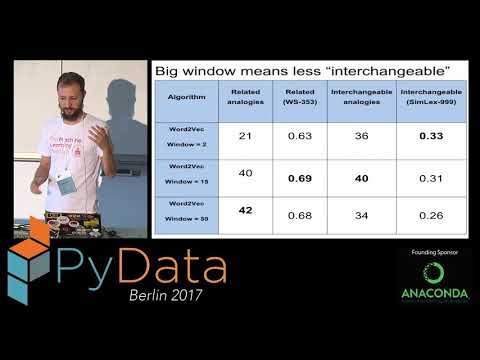
Shows concrete choices and outcomes: uses Gensim with Google's Word2vec, Facebook FastText, VarEmbed and WordRank; on a 120k‑word Pride and Prejudice corpus window=2 -> interchangeability (Wickham ≈ Darcy), window=50 -> topical attributes (Darcy → aloof, proud); FastText improves unseen or morphologically related tokens by using subword n‑grams but trains slower; WordRank (learning‑to‑rank) wins relatedness on small data though it takes much longer to train; includes code, exact params and evaluation datasets so results are reproducible.
AI-written summary · about
chapters (16)
- 0:00Gensim and word embeddings
- 1:46Text similarity for business
- 6:47Pride and Prejudice with Gensim
- 8:33Training attribute models
- 11:45Window parameter in embeddings
- 13:54Word embedding algorithms
- 16:01FastText on Pride and Prejudice
- 18:10Theory behind embeddings
- 21:40How embeddings capture meaning
- 24:56From co-occurrence to embeddings
- 27:02FastText subword info
- 29:07Evaluating FastText
- 30:33Word2Vec vs FastText vs GloVe
- 32:02Choosing embedding algorithms
- 34:54Next-gen word embeddings summary
- 35:33Q&A on GloVe
related talks
 39mNext generation of word embeddings in Gensim
 34mWord Embeddings for fun and profit in Gensim
 39mBeyond word2vec: GloVe, fastText, StarSpace
 01h 01mWord Embeddings - An Alternative & Efficient Approach to Search for Docs
 01h 03mWord Embedding For Fun and Profit
 28m"Embeddings: How Computers Learned to Read"
 01h 28mDocument/Sentence Similarity Solution
 31mText and Code Embeddings