Large Scale Vandalism Detection in Knowledge Bases
summary
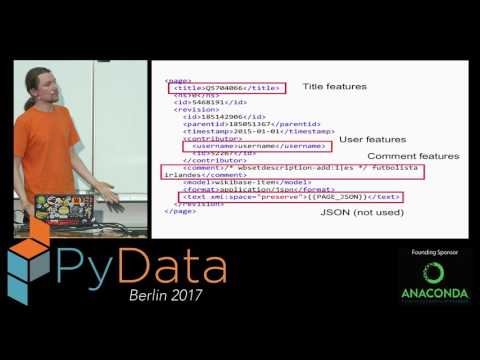
Wikidata revision dump contains 72 million edits totalling half a terabyte of revisions with only 25 basis points rollback rate so the task is extreme class imbalance. The solution parses titles, usernames and comments, uses scikit-learn linear SVMs with the hashing trick and Feather for fast IO, trains on ~35 million rows, and produces a compact production model that runs within 4 GB and achieves about 96% AUC, earning second place in WSDM Cup 2017.
AI-written summary · about
chapters (15)
- 0:00Vandalism detection intro
- 1:06Knowledge bases and RDF triples
- 3:12Wikidata vandalism problem
- 5:01Wiki Cup competition
- 7:13Data prep and validation
- 8:39Feature extraction from revisions
- 13:53Machine learning model choice
- 15:20Stacking models and imbalance
- 17:51Memory constraints solution
- 20:42Model performance results
- 21:48Lessons learned validation
- 22:53Feather for data processing
- 23:55Open-source code publication
- 24:37Industry adoption feasibility
- 25:40Q&A
related talks
 01h 18mComputer Vision after the Victory of Data
 28mData Curation: Transforming Bytes into AI Gold
 59mExploring Wikipedia with Apache Spark: A Live Coding Demo
 56mKeynote Interview
 30mData Driven Security
 39mImpacting Global Policy by Understanding Litter Data
 45mA gentle introduction to Vector Databases
 54mData doesn't lie — but it can mislead: How to ensure integrity of your Machine Learning applications