Next generation of word embeddings in Gensim

summary
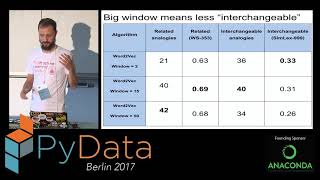
Gensim presents concrete comparisons: fastText uses subword n‑grams so unseen forms like "knights" get plausible vectors and it outperforms on interchangeable-similarity benchmarks but trains slower and inflates vocabulary; WordRank optimizes a ranking loss, wins at topical/related similarity on small corpora and can take hours for Wikipedia-scale training (example: ~40 hours on 17M words reported), while Word2Vec-style models are fast to train; Gensim supplies a stable Gensim API and wrappers so switching models keeps the same code.
AI-written summary · about
chapters (15)
- 0:00Gensim and word embeddings intro
- 2:08Defining similarity in embeddings
- 7:28Word embeddings and representations
- 11:24Generating embeddings from co-occurrence
- 15:04Training with Word2Vec
- 16:07FastText and subword info
- 20:05FastText in Gensim for new words
- 23:21FastText for complex morphology
- 25:09Beyond Word2Vec and FastText
- 27:39WordRank embeddings
- 30:12WordRank vs other embeddings
- 32:01Tuning window size
- 34:07Choosing the right embedding
- 37:46Training and evaluating tips
- 39:15Q&A
related talks
 40mText similiarity with the next generation of word embeddings in Gensim
 34mWord Embeddings for fun and profit in Gensim
 01h 01mWord Embeddings - An Alternative & Efficient Approach to Search for Docs
 39mBeyond word2vec: GloVe, fastText, StarSpace
 30m(Re)training word embeddings for a specific domain
 47mNatural language modelling- BlazingText algorithm
 31mText and Code Embeddings
 26mImplementing a Search Index