High-Performance Distributed Tensorflow
summary
Demos show concrete optimizations: 8-bit quantization and weight rounding shrink a 32k float model to ~13k and activation calibration is needed; batch-normalization folding bakes means/variances into weights to remove runtime multiplies; TFCompile plus Excel A compilation can strip a TensorFlow runtime from ~30 MB to ~600 KB for embedded inference; Graph Transform Tool runs post-training passes. Load tests compare optimized vs unoptimized models and enabling request batching (10 ms batch timeout) yields large throughput gains at the cost of added latency.
AI-written summary · about
chapters (8)
- 0:00Introduction
- 2:49High-performance TensorFlow
- 5:57CUDA streams and GPU optimization
- 9:33TensorFlow debugger and queues
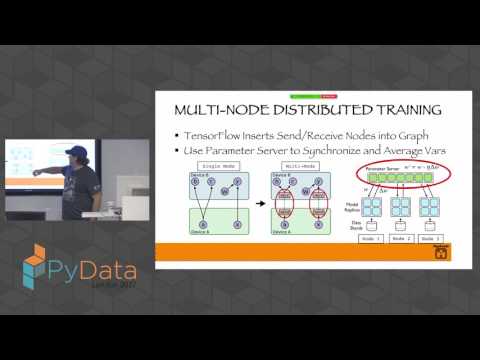
- 13:24Distributed TensorFlow
- 17:22Inference with XLA
- 24:46Model serving
- 32:20Q&A
related talks
 42mHigh Performance Distributed Tensorflow
 14mOptimize your TensorFlow Lite models
 59mBuilding models for TPU devices
 21mThings I learned running neural networks on microcontrollers
 43mTensorFlow for Mobile Developers
 34mTensorFlow Lite
 38mCutting Edge TensorFlow: New Techniques
 25mThe Golden Triangle of Inference Optimization: Balancing Latency, Throughput, and Quality