The Good, the Bad and the Ugly: The 3 Learnings of an SRE
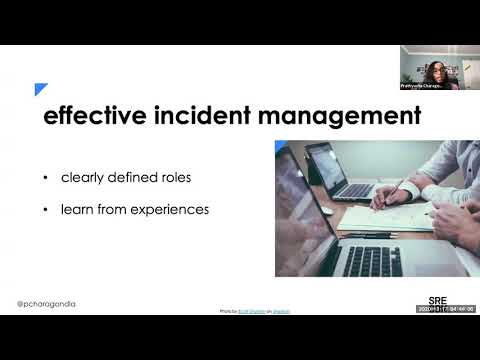
summary
Three concrete learnings: build tooling to reduce MTTD/MTTR (automated rollbacks, detection playbooks) and run controlled failures with chaos mesh / Chaos Monkey / Gremlin using hypothesis + scope + metrics; run game days quarterly to test team response. Define roles, require a postmortem write-up, and map fixes to long‑term work. Measure customer‑facing metrics with SLI/SLO/SLA, audit alerts regularly, and invite outsiders to find blind spots so monitoring gaps don’t hide outages.
AI-written summary · about
chapters (10)
- 0:00The Good, the Bad, the Ugly
- 1:03proactive reactive
- 2:01proactive approaches
- 2:46chaos engineering
- 4:53gamedays
- 6:33effective incident management
- 9:20Why is this important?
- 10:18Overview of SLI, SLO, SLA
- 13:11How can we ensure coverage? understand
- 15:59Key Takeaways
related talks
 31mSRE Theory vs. Practice: A Song of Ice and TireFire
 19mThe Never-Ending Story of Site Reliability
 29mThe Curious SRE: Cultivating a Mindset for System Resilience
 25mMental Models for SREs
 31mConfessions of an SRE Manager
 24mManaging Up and Sideways as an SRE
 13mSucceeding as the Lone SRE in a Small Team
 26mMy Life as a Solo SRE