How We Got Druid to Work at Odnoklassniki

summary
Describes replacing a 50 TB MSSQL-based analytics system with Apache Druid to fix slow queries, instability (up to 30-minute lag), and high Microsoft licensing costs. Explains using Druid, a high-performance column-oriented distributed datastore, to speed up responses (up to 20×), eliminate data lag at peak, and reduce operating expense.
AI-written summary · about
chapters (11)
- 0:00Introduction
- 4:01Old system problems
- 7:12Choosing Druid
- 7:34Druid architecture
- 12:12Fault tolerance
- 18:45Loading data into Druid
- 21:18Segment and filter tuning
- 27:55Feed query optimization
- 32:11Query prioritization
- 34:44Summary
- 35:50Q&A
related talks
 45mDruid: Powering Interactive Data Applications at Scale
 27mTales at Scale: Analytics at 1000 QPS and Beyond
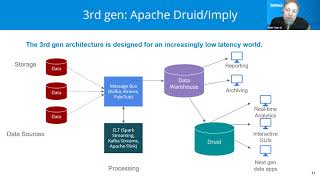 39mApache Druid 101
 27mCasting the Spell: Druid in Practice
 46mScalable Realtime Analytics using Druid
 28mThe Heat is On: Architecting for Hot Analytics
 28mCasting the spell: Druid in practice
 40mBuild Real-time Analytic Applications: The Easy Way