Build Real-time Analytic Applications: The Easy Way

summary
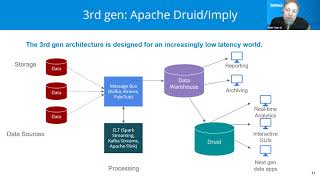
Apache Druid claims sub-second queries on streaming and historical data by building immutable columnar segments, keeping real-time shards in-memory on middle managers and loading historical segments on historical nodes, with deep storage on S3/HDFS and metadata in Postgres/MySQL. Deployment uses Helm chart + Kubernetes (statefulsets, pod disruption budgets, persistent volumes, HPA for middle managers) and pulls Zookeeper and a metadata DB as dependencies. Deployments can be as simple as cloning the repo and two helm commands; recommended minima are replica counts of two (e.g., 10 historical and 6 middle managers for larger clusters). Missing: integrated metrics and multi-tier historical automation.
AI-written summary · about
chapters (4)
- 0:00Start
- 3:40The Druid Architecture
- 14:54Apache Druid Holm Chart
- 19:28Configuration with Helm Chart druid
related talks
 46mScalable Realtime Analytics using Druid
 39mApache Druid 101
 45mDruid: Powering Interactive Data Applications at Scale
 20mAnalyzing streaming data with Apache Druid
 32mBuilding Real-time Systems with Open Source Technologies
 27mSucceeding with Apache Druid and Clickstream Data
 27mCasting the Spell: Druid in Practice
 41mBuilding an Open Source Streaming Analytics Stack with Kafka and Druid