Orchestrating Your Data Pipelines with Apache Airflow

summary
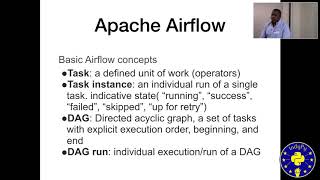
Overview of Apache Airflow with hands‑on demo: uses Docker‑based local runner and standard operators to build an S3→Athena→Redshift pipeline that ingests MovieLens files, merges three partitions with Athena SQL, runs a Python cleaning step that removes movies containing the letter “e”, and loads results into Redshift. Coverage includes scheduler semantics (start_date, catchup, cron vs timetables), stateless workers, the metadata DB for connections/variables, UI troubleshooting, and a live run that fails on a missing AWS region then succeeds.
AI-written summary · about
chapters (9)
- 0:00Intro
- 1:10What is in your data pipeline?
- 2:33Introducing Apache Airflow
- 12:11Demo
- 18:13Building our data pipeline demo
- 20:23Demo
- 30:52Apache Airflow evolution
- 31:48How to contribute
- 32:10Outro
related talks
 36mElegant data pipelining with Apache Airflow
 36mGetting Started with Apache Airflow - Building Your First Workflow
 38mUse Apache-Airflow to Build Data Workflows
 48mFlow Is in the Air: Best Practices with Apache Airflow
 42mHow I learned to time travel, or, data pipelining and scheduling with Airflow
 38mLessons Learned from the Migration to Apache Airflow
 27mModern ETL-ing with Python and Airflow (and Spark)
 44mThe Art of Data Engineering