How I learned to time travel, or, data pipelining and scheduling with Airflow

summary
Adopts Airflow as the scheduler and executor, wires Celery with RabbitMQ or Redis for distributed workers, and builds a plugin called smart_airflow to add S3 and local file backed intermediate artifacts so tasks cache outputs and remain idempotent. Production instance runs 1,300 tasks across eight active dags with 27 worker processes on an m4.4xlarge, shows useful UI, retries, pools, and alerting, but exposes hard facts like execution date ≠ start date and missing log rotation that must be handled.
AI-written summary · about
chapters (17)
- 0:00Data pipeline challenges
- 2:09Better scheduling system needed
- 5:18File dependency systems
- 8:48Orchestration systems explained
- 11:57Why Airflow over alternatives
- 13:42Airflow key features
- 17:12Airflow user interface
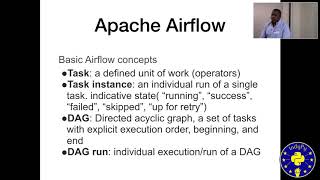
- 20:02DAGs and tasks in Airflow
- 22:11Airflow time tracking
- 26:25Alerting and monitoring in Airflow
- 28:08Airflow caching
- 29:53Getting started with Airflow
- 31:38Airflow tips and gotchas
- 33:23Airflow time concepts
- 35:55Airflow community resources
- 37:25Dynamic DAG creation
- 40:26Overcoming Airflow hurdles
related talks
 46mA Practical Introduction to Airflow
 38mUse Apache-Airflow to Build Data Workflows
 36mElegant data pipelining with Apache Airflow
 26mGo with the Flow: Automating Your Workflows with Airflow
 32mOrchestrating Your Data Pipelines with Apache Airflow
 36mGetting Started with Apache Airflow - Building Your First Workflow
 48mFlow Is in the Air: Best Practices with Apache Airflow
 46mGetting Started With Data Pipelines Using Apache Airflow