Flow Is in the Air: Best Practices with Apache Airflow

summary
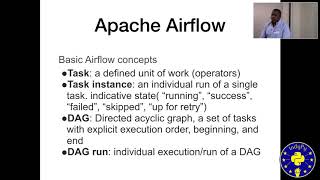
Overview of using Apache Airflow in production for over two years, showing how programmatic DAGs and a pluggable executor model turn analytics prototypes into running pipelines integrated with Hive, Spark, Kafka and Kafka Connect. Describes concrete patterns for dynamic runtime dependencies, centralized configuration, and creating plugins/extensions to add operators, plus operational details (metadata DB, local vs clustered executors), migration case studies and production-run status of those pipelines.
AI-written summary · about
chapters (7)
- 0:00Airflow workflows
- 12:12DAG components
- 20:46Workflow management
- 30:33Template management
- 33:41Configuration & metadata
- 42:40Enterprise deployment & scalability
- 47:41Q&A
related talks
 36mElegant data pipelining with Apache Airflow
 36mGetting Started with Apache Airflow - Building Your First Workflow
 32mOrchestrating Your Data Pipelines with Apache Airflow
 38mUse Apache-Airflow to Build Data Workflows
 42mHow I learned to time travel, or, data pipelining and scheduling with Airflow
 30mToo Big for DAG Factories?
 38mLessons Learned from the Migration to Apache Airflow
 44mThe Art of Data Engineering