Scaling KV Caches for LLMs: How LMCache + NIXL Handle Network and Storage...

summary
LMCache integrates with NVIDIA’s NIXL transfer library to move big K and V tensors between GPUs, CPUs, and storage using a buffer-list primitive and asynchronous non-blocking operations so transfers overlap compute. NIXL exposes registered memory (VRAM, DRAM, NVMe, object store), supports UCX/GDS/RDMA and zero-copy, and uses a metadata handshake for dynamic agent discovery. Benchmarks show wins at 1k token contexts, larger ISLs improve savings and reclaim GPU time.
AI-written summary · about
chapters (12)
- 0:00Scaling KV caches for LLMs
- 1:05Inference more critical than training
- 2:30Long context inference challenge
- 5:40Reusing KV caches across queries
- 8:28Requirements for distributed sharing
- 10:35Heterogeneous systems challenges
- 12:39NIXL buffer list design
- 15:51NIXL transfer backends and storage
- 19:22Metadata for dynamic connectivity
- 22:33Integrating NIXL with LM cache
- 23:15Performance with KV cache storage
- 24:46Q&A
related talks
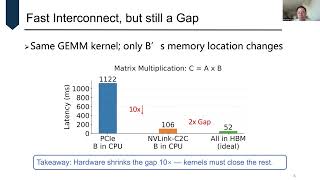 16mNo Buffer, No Bottleneck: Efficient Zero-Copy KV Cache Offloading for Long-Context LLMs
 44mVLLM K/V Caching With Ceph
 15mKV Cache: Accelerating AI Inference on Intel CPU
 23mFast Inference, Furious Scaling: Leveraging VLLM With KServe
 34mVLLM KV Cache Management: From Cache Reuse To Agent Scenario Optimization
 11mLightning Talk: Inside VLLM's KV Offloading Connector: Async Memory Transfers for...
 38mExploring Distributed Caching for Faster GPU Training with NVMe, GDS, and RDMA
 10mLightning Talk: KV-Cache Centric Inference: Building a State-Aware...