Lightning Talk: KV-Cache Centric Inference: Building a State-Aware...

summary
KV-cache centric inference reframes serving so KV state becomes the primary resource, implemented with llm-d plus vLLM, LLMCache and Envoy on Kubernetes; it uses tiered memory management (GPU → CPU → remote storage), cross-replica visibility so any instance can reuse cached prefixes, and cache-aware scheduling that routes requests to existing prefixes. Benchmarks show a conversational workload using ~70% of a 16× H100 distributed KV pool reaches near-optimal latency and cost, and authors report up to ~10× API cost reduction when prefill is cached.
AI-written summary · about
chapters (7)
- 0:00KV-cache centric inference
- 1:04Key SLOs in AI inferencing
- 2:27Attention and inference phases
- 4:57LLMD optimizations overview
- 6:22KV cache valid paths
- 9:34KV cache management strategies
- 9:55Summary and call to action
related talks
 19mBeyond the Node: Scaling Inference with Cluster-Wide KVCache...
 25mTo Cache or Not To Cache? a Tiered KVCache Storage System for Agent ...
 23mFast Inference, Furious Scaling: Leveraging VLLM With KServe
 15mKV Cache: Accelerating AI Inference on Intel CPU
 34mVLLM KV Cache Management: From Cache Reuse To Agent Scenario Optimization
 32mScaling Generative AI Inference with llm-d
 44mVLLM K/V Caching With Ceph
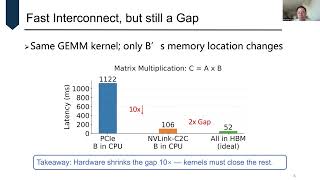 16mNo Buffer, No Bottleneck: Efficient Zero-Copy KV Cache Offloading for Long-Context LLMs