Scaling Generative AI Inference with llm-d
summary
llm-d is a Kubernetes-native serving stack that splits inference into prefill, decode and shared KV cache microservices so prefill-heavy work and memory-bound decoding scale independently; demo runs a Llama 3.2 1B backend (VLM) on OpenShift, shows KV cache aware routing with about 86% cache hit rate and ~90% session stickiness, uses Grafana/Prometheus for observability, dynamically scales decode pods and reuses a distributed KV cache so repeated prompts avoid GPU recompute and end-to-end routing/eviction behavior is implemented.
AI-written summary · about
chapters (13)
- 0:00Scaling generative AI workloads
- 2:11Large language model inference
- 4:19Monolithic LLM architecture challenges
- 6:05Introducing llm-d
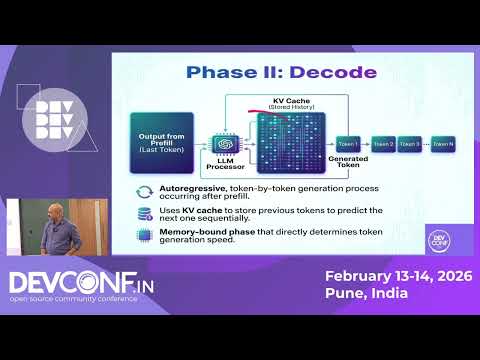
- 9:18LLM request processing with KV cache
- 11:32Microservices in llm-d
- 15:02Resource isolation for prefill/decoding
- 16:07Demo: OpenShift AI with llm-d
- 19:17KV cache-aware traffic routing
- 22:34Observability and metrics
- 25:13Q&A: Eviction strategies
- 28:52llm-d vs standard load balancers
- 31:21Summary
related talks
 33mllm-d: Kubernetes Native Distributed Inferencing
 33mBeyond VLLM: Distributed LLM Inferencing With Llm-d on Kubernetes
 38mOptimizing LLM Inference for the Rest of Us
 27mServing PyTorch LLMs at Scale: Disaggregated Inference With Kubernetes and Llm-d
 23mFast Inference, Furious Scaling: Leveraging VLLM With KServe
 08mKeynote: Plug in and Scale: Serving LLM Models on Kubernetes Ma...
 31mFrom Model Serving To Distributed Inference: How Llm-d Evolves AI Platforms on…
 33mScalable LLM Inference on Kubernetes With NVIDIA NIMS, LangChain, Milvus and Flu...