MPI Meets Machine Learning: Unlocking PyTorch distributed for scaling AI workloads
summary
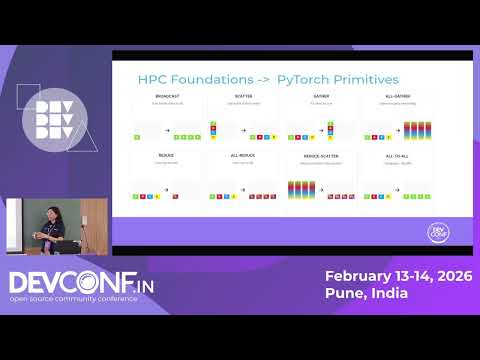
Maps MPI collectives onto PyTorch primitives and shows concrete tradeoffs: uses torch.distributed with backends NCCL Gloo or MPI, runs via torchrun/elastic, and demonstrates that optimizer state often costs ~3× model size so ZeRO 0/1/2 and sharding matter. Presents FSDP mechanics (all_gather during forward/backward, reduce_scatter for updates) and a striking example FSDP reduces 120GB→1.9GB. Notes topology tips like NCCL (NVLink ≈900 Gbps) vs InfiniBand ≈50 Gbps.
AI-written summary · about
chapters (16)
- 0:00HPC and deep learning worlds
- 3:01HPC components and parallels
- 7:13HPC and AI communication evolution
- 9:04Scaling AI across nodes
- 10:49Collective communication primitives
- 13:15MPI to PyTorch translation
- 14:39PyTorch distributed stack
- 17:25Data vs model parallelism
- 18:49DeepSpeed ZeRO optimizer states
- 20:13Fully Sharded Data Parallel
- 23:20Switching DDP to FSDP
- 24:48Tensor parallelism
- 26:34Pipeline parallelism
- 29:213D parallelism strategies
- 33:35Key takeaways
- 36:29MPI and NCCL Q&A
related talks
 24mTraining large scale models using PyTorch
 13mLightning Talk: Exploring PiPPY, Tensor Parallel and Torchserve for Large...
 08mPyTorch Distributed: Towards Large Scale Training
 31mHigh-Performance MPI and Deep Learning on OpenPOWER Platform
 40mOptimize Your AI Cloud Infrastructure: A Hardware Perspective
 14mAccelerating PyTorch FSDP Via Overlapping Collectives With In...
 19mAI/ML Networking Challenges: The Fast and the Finicky!
 25mDistributed Training in PyTorch: Zero to Hero