Lightning Talk: Inside VLLM's KV Offloading Connector: Async Memory Transfers for...

summary
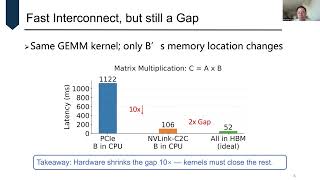
vLLM adds a pluggable KV connector that offloads KV-cache from GPU HBM to CPU DRAM using async GPU DMA transfers, exposing a stateless, block-based API enabled by the kv_offload_size option. A memory-layout redesign to a contiguous block layout increases effective block sizes by up to 125×, delivering an order-of-magnitude offloading speedup and saturating PCIe at ~60 GB/s while keeping near-zero overhead on end-to-end throughput.
AI-written summary · about
chapters (7)
- 0:00VLLM and KV offloading intro
- 1:01KV cache offloading explained
- 3:53KV offloading use cases
- 4:57KV connector interface design
- 6:42Offloading connector workflow
- 8:28Performance goals and PCIe limits
- 9:54Future work and next steps
related talks
 16mNo Buffer, No Bottleneck: Efficient Zero-Copy KV Cache Offloading for Long-Context LLMs
 15mvLLM: Easy, Fast, and Cheap LLM Serving for Everyone
 44mVLLM K/V Caching With Ceph
 34mVLLM KV Cache Management: From Cache Reuse To Agent Scenario Optimization
 40mScalable and Efficient LLM Serving With the VLLM Production Stack
 26mLMCache: Lower LLM Performance Costs in the Enterprise
 15mKV Cache: Accelerating AI Inference on Intel CPU
 33mScaling KV Caches for LLMs: How LMCache + NIXL Handle Network and Storage...