The Pain and Glory of Data Preparation
summary
Showcases concrete fixes not fluffy theory: use Excel pivot tables and Power Query to unpivot report-style rows, import a folder of CSVs into one table (he pulls together 34,000 records from over 40 files), and apply array formulas plus lookup tables to strip suffixes like "Jr" and "III." Describes finding misposted payments (examples range from $5,000 to $0.26), three practical cleansing layers (spreadsheet, ETL/database, source validation), and when to automate versus accept dirty fields.
AI-written summary · about
chapters (12)
- 0:00Data prep challenges
- 1:27Why data prep feels like sport
- 3:57Detecting duplicates
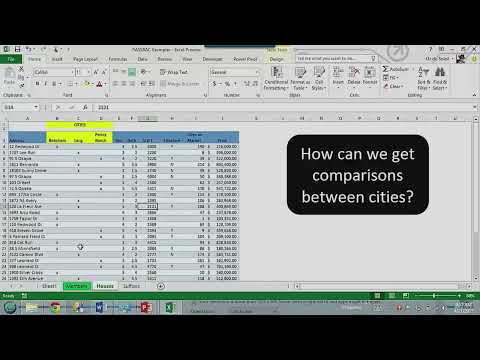
- 14:22Unpivoting city data
- 19:34Extracting last names
- 27:36Stacking CSV files with Power Query
- 30:39Sustainable cleaning strategies
- 35:44Three cleansing layers
- 40:46Clean enough standards
- 44:28Preventing bad data
- 47:16Edge cases and policies
- 51:16Q&A
related talks
 16mEXCELsioR!
 39mDoing Data: The Critical Process of Data Preparation (...)
 01h 01mDark Matter: Domain Experts & Nextgen Spreadsheets Are Our Future
 59mSelf-Service Data Modeling
 48mBest practices for developing Power BI reports
 01h 03mFrom Data to Insight – Views from Microsoft Finance
 01h 03mMicrosoft Data Explorer for Excel: Data Discovery & Transformation
 18mEmpowering Business Through Data