Why is it always DNS, TLS, and bad configs?
summary
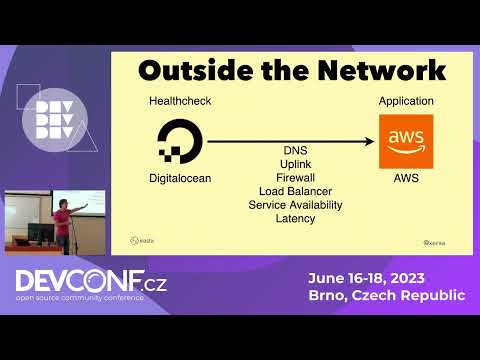
Claim: most outages trace to DNS, TLS, or bad configs, and cheap, structured health checks catch them early. Examples include a DNS TTL 24h copy-paste outage that slowly erased records, a recurring TLS cert expiry repeated yearly (Gradle), and spine-region rollouts that exposed Cloudflare bugs. Built a heartbeat-style monitor that runs ICMP/TCP/HTTP checks every 5–10s, TLS-expiry alerts (e.g., warn 15 days out), and Playwright-based synthetic user flows every few minutes; these detect redirects, latency shifts, and broken flows before users complain.
AI-written summary · about
chapters (11)
- 0:00Introduction
- 1:04DNS failures and TTL delays
- 2:32TLS certificate expiration
- 4:17Facebook outage causes
- 5:41Cloudflare spine bug lessons
- 6:42Health checks as solution
- 10:34Elasticsearch health tools
- 12:43Live demo: health check monitoring
- 17:16Synthetic monitoring tests
- 23:18Health checks vs observability costs
- 24:40Summary and Q&A
related talks
 22mWhy is it always DNS, TLS, and bad configs?
 28mMy Favourite Errors
 32mCustomer Centric Monitoring
 29mSex, Lies & Videotapes: The Truth Behind Your CDN Logs
 36mLogs Told Us It Was DNS, It Felt Like DNS, It Had To Be DNS, I...
 27mSoftware won't make noise when it breaks
 45mHello from the other side
 07mTest Measure Iterate - Balancing “Good Enough” & “Perfect”