Why is it always DNS, TLS, and bad configs?

summary
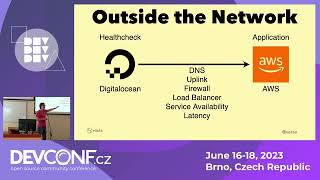
Claim: outages usually trace to DNS, expiring TLS, or misconfiguration. Demonstrates layered health checks—external, internal, host—with concrete checks: ICMP/TCP/HTTP probes, TLS expiry checks, end-to-end POST that verifies DB writes. Mentions real incidents (Akamai DNS drift, Microsoft deleted certificate, Facebook BGP/config failure) and a demo showing 32 services, 4 down. Uses AWS backend, DigitalOcean probes and Playwright for synthetics, pings every 5s, and shows that cheap, frequent checks detect root causes early.
AI-written summary · about
chapters (6)
- 0:00Start
- 6:05Structure Your Health Checks
- 7:33Latency
- 8:31Is tls Still Valid
- 14:29Synthetic Monitoring
- 20:35Health Checks
related talks
 31mWhy is it always DNS, TLS, and bad configs?
 28mMy Favourite Errors
 32mCustomer Centric Monitoring
 28mReliability Lessons from Running High Traffic Services for More Than 10 Years
 22mBest Practice: DNS Failure Observability and Diagnosis in Kubernetes
 27mSoftware won't make noise when it breaks
 51mDesigning for Failure: Build Resilient Services
 45mLet's play a real life Dungeon and Dragons