Key Considerations For Success When Deploying A Solution For Best-of-breed Observability At Scale
summary
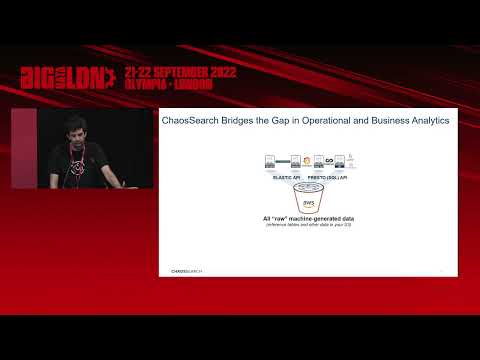
ChaosSearch positions an operational data lake that keeps raw logs in customer cloud storage and reads them back as a cloud storage passive read, transforms into an internal format and leaves data at rest with the customer. It claims 90% cost savings versus centralized observability by separating fast detection (Prometheus/Grafana) from large-scale analytics, offering Search and SQL APIs and integrations (OpenSearch Dashboards, Superset) with minutes ingest / seconds queries for JSON and semi-structured telemetry retained indefinitely without per-ingest billing.
AI-written summary · about
chapters (5)
- 0:00Introduction to observability challenges
- 2:49Centralization issues at scale
- 5:57Passive read approach for scalability
- 8:48Beyond observability to business value
- 12:37Customer success and Q&A
related talks
 15mThree key considerations for deploying best-of-breed observability
 35mFrom Chaos To Clarity: Centralizing Observability With OpenSearch at Scale
 12mOpen-source observability is the way forward, and here’s why
 21mKubernetes Under the Magnifying Glass: Observability With OpenSearch
 24mWhat Observability Can Learn From BI
 06mSponsored Keynote: OpenSearch - See Everything: Open Observability for Agentic AI
 42mObserve Smarter, Not Harder: Scaling AI-Powered Observability With O...
 37mBuilding Modern Observability Architecture With OpenSearch, OS Ingest...