The Curse of SRE Autonomy and How to Manage It

summary
A ten‑year internal scheduler called Sisyphus becomes widely adopted across SRE teams despite no roadmap, poor Python code, and leadership trying to retire it; adoption is measured by rising commits per author ratio across teams over years. Success rests on three concrete facts: it requires teams to subclass and build their own binary so each team owns a service, a plug-in architecture lets teams keep existing CLIs, and its pragmatic “works well enough” scaling (spin up more instances) solves urgent, high‑toil rollout problems.
AI-written summary · about
chapters (9)
- 0:00Introduction
- 1:58Sisyphus adoption overview
- 4:49SRE best practices defied
- 7:20Red Queen challenge 2007-2008
- 13:24Autonomy curse in SRE
- 18:03SRE autonomy evidence
- 22:19Balancing autonomy vs standardization
- 23:05Sisyphus and SRE tribalism
- 27:41Conclusion & Q&A
related talks
 45mClearing the Way for SRE in the Enterprise
 26mFrom Nothing to SRE: Practical Guidance on Implementing SRE in Smaller Organisations
 51mThe Evolution of Site Reliability Engineering
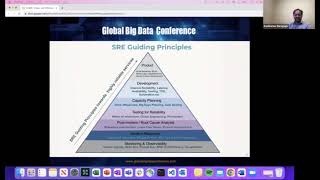 25mSRE Guiding Principles & Transformational Framework
 31mConfessions of an SRE Manager
 35mCare and Feeding of SRE
 24mBeing Reasonable about SRE
 20m5 Agile practices every SRE team should adopt