Inside NVIDIA’s AI infrastructure for self-driving cars
summary
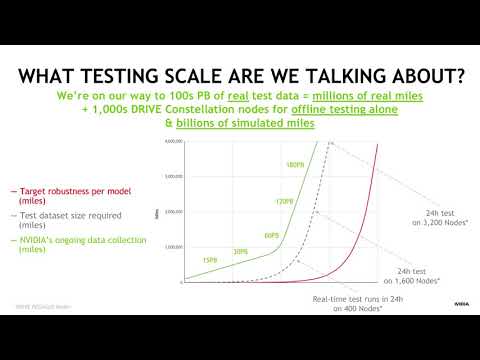
NVIDIA describes Project MagLev as an internal AI platform that ingests multi‑PB road data from ~30 cars with 12 cameras each, runs active‑learning selection and labeling (1,500 labelers, ~20 million objects/month), and schedules training/testing across 4,000 GPUs (≈500 petaflops) on a hybrid AWS + on‑prem DGX rack architecture with S3 object storage and local caching. Pipelines are Kubernetes‑managed, reproducible workflows for dataset versioning and model analytics, and the team pairs that with the open GPU‑data stack RAPIDS (including cuDF, cuML, cuGraph) to keep data in GPU memory and speed end‑to‑end.
AI-written summary · about
chapters (16)
- 0:00Intro
- 0:57NVIDIAs selfdriving strategy
- 3:23Why is this challenging
- 5:40The scale of testing
- 6:56The data
- 9:31Challenges
- 11:28Data set lifecycle management
- 12:23Two worlds
- 14:07Kubernetes
- 15:22Automation
- 18:42Data selection
- 20:47Hardware
- 22:30Aanthor Granola
- 25:21Endtoend benchmarks
- 26:59Open source
- 27:37Hiring
related talks
 26mInside NVIDIA’s AI Infrastructure for Self-driving Cars
 28mMagLev: A Production-grade AI Platform Running on GPU-enabled Kubernetes Clusters
 20mAccelerating AI pipelines w/ NVIDIA on AWS: An autonomous driving case
 05mInterview
 40mFueling the AI Revolution with Gaming
 42mAI and Self-Driving Cars
 21mML Infrastructure for Autonomous Vehicles
 28mDeveloper Essentials for the New Era of AI