MagLev: A Production-grade AI Platform Running on GPU-enabled Kubernetes Clusters

summary
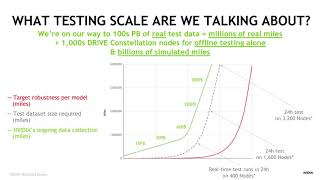
MagLev is NVIDIA’s production platform that ingests multiple terabytes per hour and manages petabyte-scale datasets to run training, replay and simulation at scale. It uses Kubernetes + object storage (SwiftStack/S3), snapshots data as immutable datasets, schedules jobs across DGX racks and a 10,000+ GPU fleet, and coordinates 1,000+ human labelers with automated curation and active learning. A racked Drive Sim setup runs real-time software-in-the-loop tests, CI-style validation and reproduction, and the platform is deployed and operating in production.
AI-written summary · about
chapters (8)
- 0:00Introduction to Nvidia Drive
- 2:00Challenges in AV development
- 5:19Data scale and infrastructure
- 9:03The Maglev platform overview
- 12:04Maglev technical architecture
- 15:27Data curation and labeling
- 20:38Model training and simulation
- 24:09Deployment and compute power
related talks
 26mInside NVIDIA’s AI Infrastructure for Self-driving Cars
 32mInside NVIDIA’s AI infrastructure for self-driving cars
 25mEmpowering AI-Driven Drug Discovery: Overcoming Challenges in Building a ML Platform on Kubernetes
 31mKubernetes For GPU Powered Machine Learning Workloads In Academia
 34mScaling AI Like a Pro-PepsiCo’s LLM Deployment Strategy on K...
 30mRun Your Own AI Cluster on a DGX Spark: Kubernetes, GPUs, and DRA
 36mAccelerating High-Performance Machine Learning at Scale i...
 09mTransform Your Kubernetes Cluster Into a GenAI Platform: Get Ready-t...