An Occam's Razor Principle for Transformers?
summary
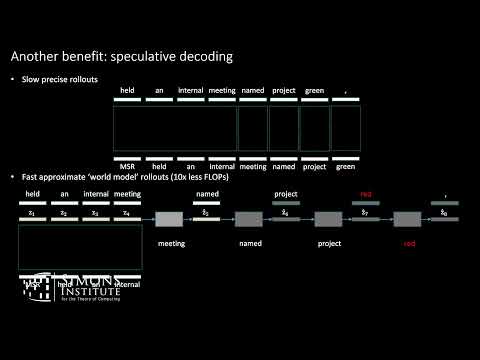
Claim: predicting the next hidden activation (not just the next token) produces a compact implicit world model that cuts extrapolation error about threefold on a Manhattan taxi task (baseline ~15% failures to reach the goal down to ~5%). Method: add a shallow unembedding head and train a next-latent prediction objective alongside next-token loss, use online-style training with progressive validation (single pass, shuffled data) and speculative decoding. Also shows ~20% accuracy boost on the 24 arithmetic task.
AI-written summary · about
chapters (10)
- 0:00Introduction
- 1:08Progressive validation in training
- 6:55Progressive validation relevance
- 8:42Implicit world models
- 17:20Transformers as world models?
- 21:41Taxi dataset experiment
- 27:23Occam's razor and extrapolation
- 30:31Future directions
- 33:32Next latent prediction for arithmetic
- 36:08Summary
related talks
 58mThe Pitfalls of Next-token Prediction
 36mNeural Networks
 34mBeyond Transformers - Intro to RWKV Architecture & The World To...
 01h 00mReducing the Dimension of Language: A Spectral Perspective on Transformers
 46mLearning Theory of Transformers: Generalization and Optimization of In-Context Learning
 01h 10mIntroduction to Transformers
 01h 30mToward Understanding In-context Learning
 01h 16mHow Do Transformers Work?