Reducing the Dimension of Language: A Spectral Perspective on Transformers

summary
Argues that sequence data can come from high‑dimensional linear dynamical systems yet admit a low‑dimensional spectral representation (about 30 effective components estimated from ~10^12 tokens/parameters). Uses Hilbert‑matrix eigendecay and fixed spectral filters plus convex regression to learn marginally stable systems with vanishing error on synthetic long‑memory tasks, and applies FFT and block/tensor factorizations to cut amortized decode cost to roughly log^2 L (practically sqrt(L)). Shows a 500M model trained on ~10B tokens that matches baselines on small evals and that tensorized filters improve length generalization.
AI-written summary · about
chapters (11)
- 0:00Introduction
- 1:19The intelligence of prediction
- 2:48Dimensionality of language
- 4:52Transformers vs RNNs
- 8:15Dynamical systems perspective
- 10:22Learning algorithms for LDS
- 15:55Spectral filtering theory
- 21:20Mathematical proofs of decay
- 31:15Neural architecture experiments
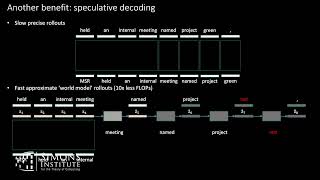
- 37:16Inference and generation
- 43:28Length generalization
related talks
 40mAn Occam's Razor Principle for Transformers?
 01h 03mRecent Progress in High-Dimensional Learning
 26mRethinking the Transformer: Toward Native Multimodal Architectures
 01h 26mFrom RNNs to Transformers: A Journey through Language Modeling
 56mTensor Decompositions for Estimating Latent Variable Models
 31mBuilding Large-scale Localized Language Models
 56mTensor Decompositions for Learning Latent Variable Models I
 53mSelf-Supervised Learning in Transformer Models for Birdsong