DeepSeek-R1 Thoughtology: <Thinking> about LLM Reasoning
summary
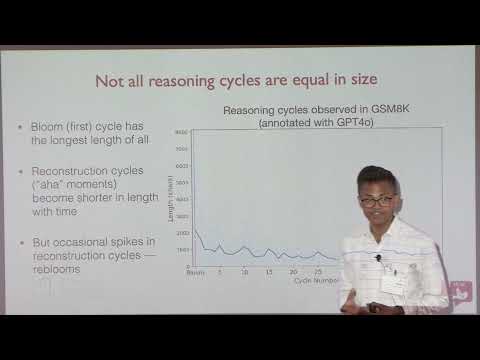
DeepSeek R1 produces long internal “thoughts” with an initial Bloom step that finds a first solution and repeated Reconstruction cycles (reblooms and rumination) that often verbatim-repeat reasoning; inference-time scaling shows accuracy rises to a sweet spot then falls. The deployed RL objective uses only formatting+final-correctness reward, so credit goes equally to every token. Replacing value nets with stepwise Monte‑Carlo rollouts (ground truth from 256 rollouts, practical estimate with ~9) as VinePPO gives far better per-step value estimates, shorter chains, and measurable gains on MATH/AIME compared to GRPO/PPO.
AI-written summary · about
chapters (9)
- 0:00DeepSeek R1 introduction
- 1:08DeepSeek R1 thoughts efficiency
- 5:10Thoughts structure
- 14:54Inference scaling trade-offs
- 27:16Credit assignment
- 36:31PPO and credit assignment
- 43:52Value networks VinePPO
- 53:14Nano R1 applications
- 59:36Q&A
related talks
 32mScaling Test-time Inference Compute & Rise of Reasoning Models
 24mThe Rise of Reasoning Models
 29mThe Evolution of LLMs: From Imitation to Reasoning
 31mBeyond LLMs and Maturing RAG use cases
 31mMaking the most of test-time compute in LLMs
 44mApropos DeepSeek
 31mMachine Reasoning and System 2 Thinking
 15mOlmo-Thinking: Training a Fully Open Reasoning Model