How We Drained Every Backbone Router Simultaneously
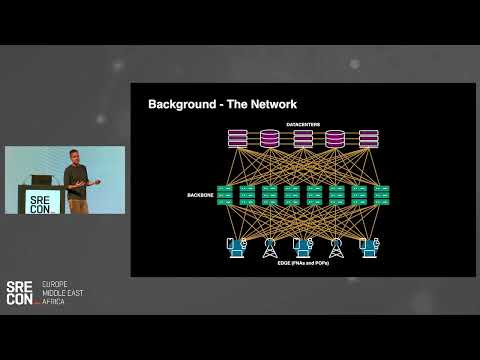
summary
On October 4, 2021 a single operator command that listed all data planes triggers a safety-check bug and drained all eight data planes in seconds, knocking out backbone connectivity for ~6 hours. DNS stops advertising via BGP so internal tooling, VPN and badging fail, forcing teams to use ad-hoc external monitors, drive to sites and perform physical data-center access required. Response includes backbone-manager automation fixes, a month-long network code freeze, canary and Defcon feature toggles plus better out‑of‑band access and testing.
AI-written summary · about
chapters (23)
- 0:00October 4th outage intro
- 2:59Agenda
- 5:47Reliability team structure
- 6:29Meta’s backbone network
- 9:18Express backbone operations
- 10:28What happened
- 13:41Initial response
- 15:30Physical access recovery
- 17:15Power spike prevention
- 18:21Storm drills benefits
- 20:30Defcon switches capacity
- 22:36Lessons from incident
- 23:41Post-incident actions
- 24:45Code freeze fixes
- 25:48Improving storm process
- 26:30Testing service recovery
- 27:15Blameless culture role
- 27:56Incident response roles
- 28:39Config change defense
- 29:20Reliability program insights
- 30:49Top production issues
- 32:12System complexity risks
- 33:15Sev trends discussion
related talks
 12mHow We Drained Every Backbone Router Simultaneously
 18mThe worst outage I never caused
 22m10x Backbone: Scaling Backbone Connectivity to Serve AI Demands
 41mImpact of Network Automation
 24mBlink: Fast Connectivity Recovery Entirely in the Data Plane
 11mRunning BGP in Data Centers at Scale
 22mBGP Vortex: Update Message Floods Can Create Internet Instabilities
 04mLoad balancing through the years