The Linear Algebra of Deep Learning
summary
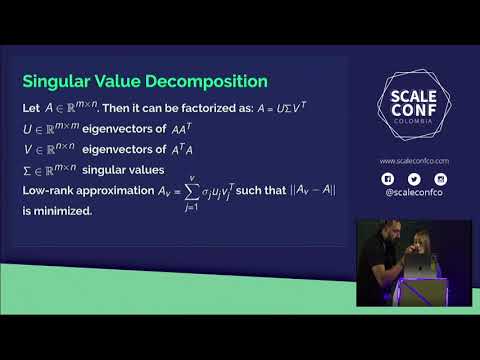
Explains how the core components of neural networks and deep learning are fundamentally operations from linear algebra. Covers matrices, vectors, and linear transformations as the basis behind layers, activations, and other network elements to show why seemingly complex or nonlinear behavior still relies on linear-algebraic building blocks.
AI-written summary · about
chapters (11)
- 0:00Introduction
- 1:31Machine learning as linear algebra
- 3:00Key deep learning algorithms
- 5:53Singular value decomposition
- 12:01Example with satellite image
- 17:02Randomized SVD algorithm
- 20:45General matrix multiplication
- 26:24Derivatives in neural networks
- 28:53Automatic differentiation explained
- 31:42Application in satellite data
- 33:07Resources and closing
related talks
 32mA Primer (or Refresher) On Linear Algebra for Data Science
 43mThe Linear Algebra of Deep Learning
 01h 00mAdventures in Linear Algebra++ and Unsupervised Learning
 41mUnveiling the simple math that powers AI
 51mDeep Learning - What is it and What It Can Do For You
 34mThe physics of deep learning using tensor networks
 54mIntroduction to Understanding Deep Learning
 35mA Crash Course in Applied Linear Algebra