Serverless: Making Sense with a Cloud Paradox
summary
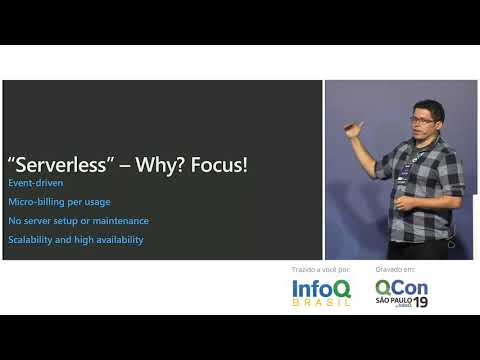
The talk explains when, how, and why to adopt serverless technologies by examining the three core pillars: event-driven architectures, micro-billing, and self-scaling abstract infrastructure. It also distinguishes how the developer experience changes and boosts productivity, and reviews architectural patterns to help introduce serverless into new or existing projects.
AI-written summary · about
chapters (21)
- 0:00Serverless introduction
- 2:55Cloud computing evolution
- 5:23Traditional infra problems
- 6:04Cloud service models
- 7:29Serverless origins
- 8:14Serverless architecture elements
- 10:46Functions and events
- 12:31Database as a service
- 14:35Event flows and automation
- 16:20Serverless technologies
- 18:04Function performance challenges
- 20:54Development best practices
- 22:17Java advanced optimizations
- 24:46Knative project
- 26:13Live demo
- 33:55Scalability and load testing
- 38:14Costs and financial predictability
- 41:51Hybrid Serverless architectures
- 42:32Have I Been Pwned case study
- 43:39Caching to reduce costs
- 44:43Conclusion and next steps
related talks
 52mWhy Serverless?
 46mServerless approach to software architecture and development
 58mServerless - the brief past, the bewildering present, and the beautiful (?) future
 34mThinking serverless: From business problem to Serverless solution
 41mWhy the fuss about serverless
 42mServerless and Its Condiments
 32mServerless Architecture
 44mMy Serverless Application