Real-time Data Processing with Apache Spark Structured Streaming
summary
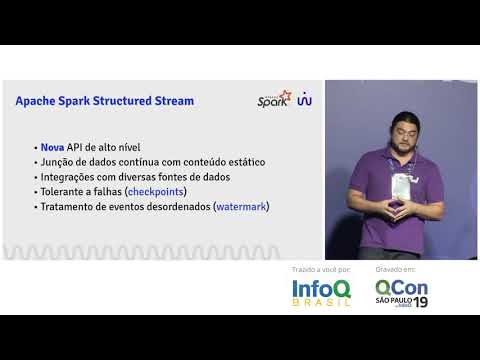
Apache Spark Structured Streaming is presented as a scalable, simple API for real-time-style processing, transformation and aggregation of large transaction volumes. The talk explains using Structured Streaming to process over 100 million tariff-attempt transactions per day, and describes the processing architecture and stream-related considerations useful for transforming large datasets.
AI-written summary · about
chapters (13)
- 0:00Start
- 2:57Introduction to Apache Spark
- 6:11Apache Spark Structured Stream
- 13:08Output Modes, data output
- 14:02Types of Output Sinks
- 15:52Fault Tolerance with Checkpoints
- 17:00Handling Out-of-Order Data
- 26:00Processing (Spark SQL API) v1
- 28:33Processing (Spark SQL) v2
- 29:50Output Data Source
- 32:47RESULTS OBTAINED
- 35:02EVOLUTION
- 37:04Performance Check
related talks
 01h 01mApache Spark Structured Stream: A Near-Real-Time Data Grinder
 42mBuilding Robust Streaming Data Pipelines with Apache Spark
 45mFrom Big Data to Fast Data: Apache Spark
 44mApache Spark on Azure - solution (...)
 52mSolving Analytical Problems using Apache Spark
 20mStreaming Architectures
 08mReal-Time Data Systems: Speed, Scale, and Resilience
 41mStreaming: an Alternative to CRUD & Batch Processing