A Guide to Modern Hyperparameters Turning Algorithms

summary
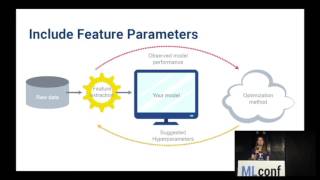
Covers concrete methods and results: compares grid/random/Bayesian search, shows HyperBand/ASHA early-stops bad trials and reports running 20+ samples with 4–8 concurrent trials on 16 GPUs across 2 nodes, describes Population Based Training copies weights and mutates hyperparameters and cites nontrivial gains over published NLP/GAN/RL baselines, and demos Tune integrated with Ray and Hyperopt that scales across nodes with Ray, logs TensorBoard, and combines BO with early-stopping for faster, resource-efficient tuning.
AI-written summary · about
chapters (20)
- 0:00Hyperparameter tuning intro
- 1:57Why hyperparameters matter
- 3:24Key tuning techniques
- 4:05Grid search strengths and limitations
- 5:30Random search benefits
- 6:12Bayesian optimization explained
- 9:44Hyperband early stopping
- 12:08Population-based training
- 15:21Ray Tune library intro
- 18:13Demo setup with Ray Tune
- 23:31Random search with Ray Tune
- 24:57HyperOpt + Ray Tune
- 27:13Async Hyperband scheduling
- 29:09Q&A preprocessing/tuning
- 30:35Q&A population mutations
- 32:27Q&A score smoothness
- 34:33Q&A export best params
- 35:46Q&A scaling depth
- 37:12Q&A validation sets
- 37:53Closing remarks
related talks
 25mHyperparameter Tuning and Visualization in Deep Learning
 18mBest Practices for Hyperparameter Optimization
 26mModel Selection with Python: An Introduction to Hyper Parameter Tuning
 03mDBTB INT Scott Clark r
 18mAlexandra Johnson, Software Engineer, SigOpt, NYC 2017
 27mAutomating XGBoost Hyperparameter Tuning with Agentic AI
 41mOptimizing Machine Learning Models
 15mAI-Driven Application Optimization