Efficient Minimax Optimal Strategies for Universal Prediction
summary
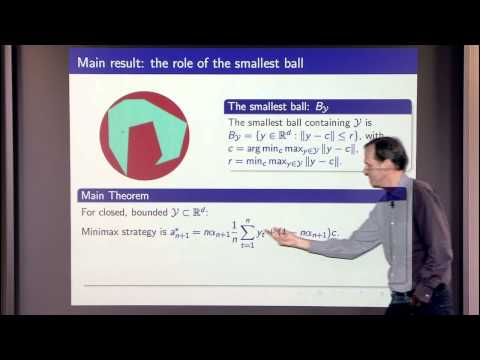
Shows when the minimax-optimal strategy is computable and what it actually is: a dynamic-program recursion yields normalized maximum likelihood as the unique optimal joint for log loss and this sequential NML is optimal exactly when the induced process is exchangeable, which is equivalent to a Bayesian rule with Jeffreys prior under asymptotic normality. For squared Euclidean loss the predictor shrinks toward the center of the minimal enclosing ball and regret depends only on its radius. For fixed‑design linear regression the minimax rule is linear using sufficient statistics with value equalizer formula sum y_t^2 x_t^T C_t x_t.
AI-written summary · about
chapters (6)
- 0:00Introduction to prediction
- 4:22Outline of talk
- 7:14Log loss and NML
- 16:08Euclidean loss
- 19:20Online linear regression
- 26:31Closing and Q&A
related talks
 55mLearning Minimax Estimators Via Online Learning
 01h 23mImplicit Regularization II
 17mCodifying Data Science Intuition
 01h 00mMin-Max Optimization from a Dynamical Systems Viewpoint
 11mLinear Predictors in Reinforcement Learning: ...
 09mTowards Credible and Effective Data-Driven Decision-Making
 45mEfficient Profile Maximum Likelihood for Universal Symmetric Property Estimation
 41mTransfer learning via local convergence rates of the nonparametric least squares estimator