Logging at Scale, Billion+ messages, 100K msg/sec

summary
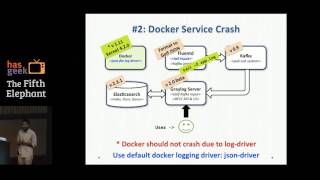
Centralized logging pipeline handling 100K msg/sec and billion-plus messages/day built with Docker -> Fluentd (initial) -> Kafka -> Graylog -> Elasticsearch; problems included Docker daemon crashes from Fluentd backpressure, a slow Fluentd Kafka plugin (~5–10k/s), and 3 MB JSON lines that broke Lucene. Fixed by truncating fields to 8KB, sending GELF into Kafka, replacing Fluentd with Go-based Heka (10x memory and throughput), and topic-partitioning Kafka for isolation — solution scales and runs in production.
AI-written summary · about
chapters (9)
- 0:00Introduction to log scaling
- 1:56Graylog features and design
- 4:23Pipeline architecture
- 7:17Solving pipeline bottlenecks
- 10:07Stability and Docker crashes
- 11:21Message size and data types
- 16:25Simplifying log buffers
- 18:03Hecka and decentralization
- 21:27Q&A and final summary
related talks
 21mLogging at scale using Graylog - Billion+ messages, 100K req/sec
 46mBuilding a scalable logging platform
 48mLogging and ranting
 22mPetabyte Scale Logging with Fluentd and Fluent Bit: A Use Case From...
 09mLightning Talk: Fluentd at Scale; Keys to successful Logging Syndication
 30mData @Scale Seattle- Sundaram Narayanan
 31mThe Long and Winding Road to Application Logging [A]
 20mFast log management for your apps