Importance of data in the time of LLMs

summary
Claim: LLMs let teams skip months of data collection by prompting or synthetic generation, but production needs benchmarks and cost controls. Example: YouTube experiments classify “is this video part of a series” using only titles, 10 examples in the prompt, a smaller 8B model in batch, and hits about 0.88 accuracy on a golden benchmark. Pipeline choices include synthetic data augmentation for rare cases and swapping LLM embeddings into cheaper downstream models to cut inference cost.
AI-written summary · about
chapters (18)
- 0:00Keynote on LLMs and data
- 1:26Daily ML interactions
- 3:13Zero-data ML possible
- 3:37Why data remains critical for machine learning
- 5:45Raw data to ML inputs
- 7:11Data collection evolution
- 9:23Data processing for ML
- 11:51LLMs vs traditional ML
- 13:38Prompt tuning for LLMs
- 14:43ML model development hurdles
- 15:48LLMs for data collection
- 17:56LLM production challenges
- 20:22YouTube LLM baseline
- 23:56Fine-tuning LLMs vs ML
- 25:46LLM risks in practice
- 26:48Beyond task-specific models
- 28:35How much data is needed for machine learning today
- 28:58Q&A: Fine-tuning vs ML
related talks
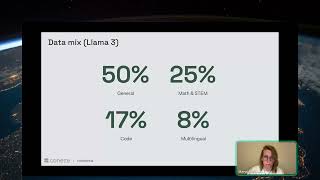 28mThe Data That Shapes Foundational LLMs
 12mKeynote: How LLMs Have Changed the Way Organizations Do AI
- 12mKeynote: How LLMs Have Changed the Way Organizations Do AI
 30m🤯 No data? No problem! Synthetic data to the rescue
 24mLLM Inference Optimization From Simple To Sophisticated
 50mPanel: Storage Systems in the LLM Era
 30mLLMs: Beyond the Hype - A Practical Journey to Scale
 28mAre LLMs the answer to all our problems?