Inside MoE Optimization: A Profiler-Guided Tour of torch.compile and vLLM
summary
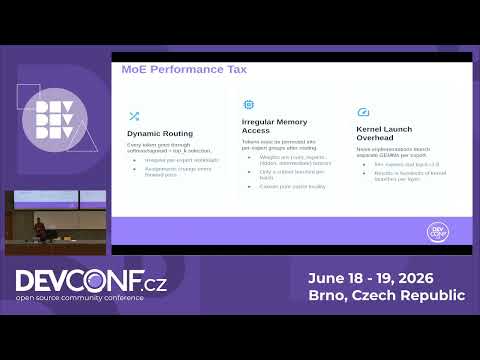
Shows a concrete pipeline that combines torch.compile + vLLM with hand‑written custom ops and CUDA graphs, yielding a fused MOE kernel that drops ~15–20 kernel launches down to two and accounts for 46% of runtime in the profile. Uses FX/Inductor passes, contiguous 3D expert weight layout, piecewise backend with batch‑size ranges to avoid Dynamo recompiles, and CUDA‑graph replay; Cutlass grouped GEMM contributes ~25% of time, GPU utilization hits 91.91% while CPU impact falls to 4.3%.
AI-written summary · about
chapters (11)
- 0:00MoE optimization intro
- 1:04MoE architecture & routing
- 4:12Hidden costs in inference
- 6:39vLLM serving optimizations
- 8:25Custom ops & torch.compile
- 11:17Dynamic batch handling
- 13:07Kernel fusion for MoE
- 15:14Memory & shape optimizations
- 17:04torch.compile for MoE
- 19:34vLLM backends breakdown
- 22:24GPU profile insights
related talks
 24mOptimizing CPU LLM Inference in PyTorch: Lessons From VLLM
 23mBlazing Fast GenAI Inference With Torch.compile
 20mUnlocking Performance: Harnessing LLMs To Streamline GPU Kernel Development in...
 25mMojo + PyTorch: A Simpler, Faster Path To Custom Kernels
 36mDL Compiler Panel Discussion
 22mOptimizing Large MoE Inference on NVIDIA Blackwell: NVFP4, ADP, and DualPipe Strat...
 12mLightning Talk: Accelerating Inference on CPU with Torch.Compile
 32mTaming the Machine: Basics of ML Models Training and Inference Optimization