How to stop worrying & collect early banner ads!
summary
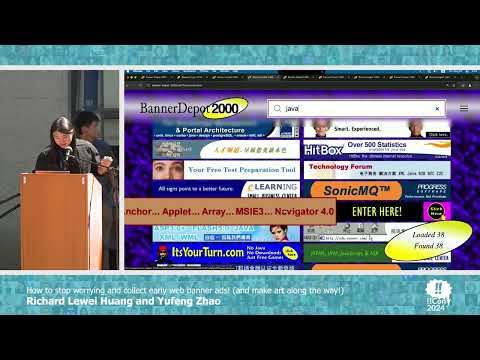
Built an interactive archive called Banner Depot 2000 that scrapes the Wayback Machine using ~77,000 URLs from printed internet directories and extracts images with a Python pipeline that reads MHTML files and runs OCR. The project publishes an open dataset of 22,915 banner ads, exposes size and date metadata, offers search and browsing, and includes a generative tool for banner ad poetry; the archive and tools are online and demonstrably functional.
AI-written summary · about
chapters (8)
- 0:00Banner Depot 2000 intro
- 1:22Motivation for collecting banners
- 3:05Extracting URLs from directories
- 4:50Building early web archive
- 5:33Live demo: search engine
- 7:46Banner ads to poetry
- 8:51Live demo: poetry generator
- 9:12Project sharing & future plans
related talks
 34mScraping Techniques to Extract Advertisements from Web Pages
 34mScraping Techniques to Extract Advertisements from Web Pages
 16mBeyond the surface: uncovering hidden threats in online ads
 49mInternet Archive: More than the Wayback Machine
 14mEverything Always Everywhere
 15mBeyond the banner: The power of Web AI to personalize paid rich media ads
 28mBiodiversity and Web Futures
 37mA Developer's Guide to Advertising