"In the Belly of the Whale: Operations at Twitter"
summary
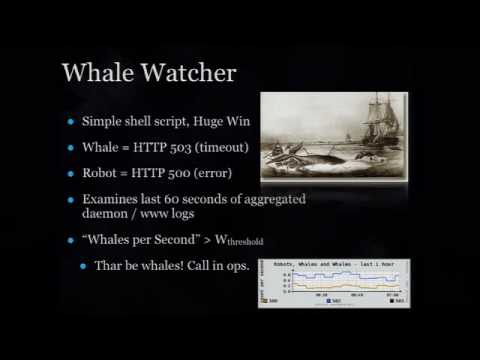
Operations at Twitter explains why the site handles ~65 million tweets per day and peaks near 3,000 tweets/sec by rebuilding the social graph, sharding with gizzard, and moving logs from syslog into scribe → HDFS → Hadoop for analysis. Uses Apache, Rails, memcache, Kestrel queues, Ganglia, Puppet, Review Board, Paro, Looney inventory, and a peer deploy tool called Murder. Unicorn cuts CPU and memory by about 30% and enables zero downtime deploys while dark mode switches (about 90 switches) let features be toggled off to recover quickly.
AI-written summary · about
chapters (8)
- 0:00Intro
- 5:31Methods on how we get data
- 7:48Analytics
- 9:58Deploys
- 12:34Subsystems
- 19:38Opportunities
- 20:15Problems
- 22:11Closing
related talks
 29mHow We Built a Framework at Twitter to Solve Service Ownership & Improve Infrastructure Utilization
 40mHacking the Pachyderm: Scaling Servers and People
 37mHow Small Changes Can Make Huge Waves
 26mRise of the Machines Security Automation at Twitter
 26mMonolith-ifying perfectly good microservices
 29mBowerbirds of Technology: Architecture and Operations at Less-Than-Facebook Scale
 47mScaling: from 0 to 25 million users
 33mHerding Elephants