Peregreen – modular database for efficient storage of historical time series...
summary
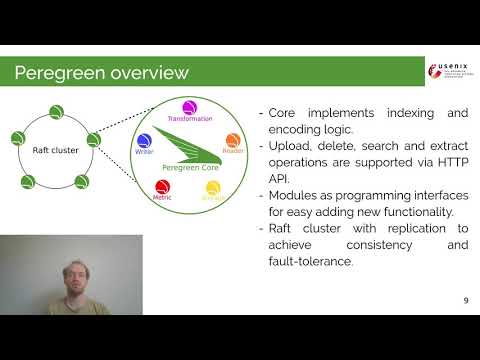
Peregreen is a modular distributed time-series database that stores all data on Amazon S3 and minimizes backend I/O with a three-tier index, per-sensor indices, and read-optimized delta+Zstd encoding that stores timestamps and values together. It achieves 3 million entries/s upload and 48 million entries/s extraction on EC2 in the authors’ tests, produces about 4× compression versus raw input, uses HashiCorp Raft for consistency, outperforms ClickHouse/InfluxDB on extraction throughput, and shows S3 often beats EBS for large reads.
AI-written summary · about
chapters (15)
- 0:00Intro
- 0:22Motivation
- 0:52Requirements
- 1:21Proposed approach
- 1:52Three-tier data indexing
- 3:25Index metadata Block
- 5:03Read-optimized series encoding (II)
- 7:30Peregreen overview
- 9:30Peregreen core. Search
- 11:10Peregreen core. Extraction (II)
- 12:41Peregreen modules
- 14:12Peregreen cluster
- 15:35On-premise: Uploading Initial data volume - 750 GB
- 16:51Amazon EC2: Extraction S3 efficiency compared to EBS
- 17:45Conclusion
related talks
 30mScaling Time-Series Data to Infinity: A Kubernetes-Powered Solution with Envoy
 39mA New Data Model for Time Series Data Processing
 30mCatching Waves with Time-Series Data
 39mTimescaleDB: Re-engineering PostgreSQL as a time-series database
 58mIntroduction to Timeseries Databases
 53mEfficient Time Series with PostgreSQL
 15mAn Efficient Cloud Storage Model with Compacted Metadata Management for Performance...
- 39mA New Data Model for Time Series Data Processing