Reinforcement Learning - What it is and How it Works

summary
Walks through a concrete policy gradients example that starts with probability .5 then shifts to .6 then to .2 by updating a single bias, multiplies a calculated derivative by a reward of +1 or −1 to flip direction, and plugs the updated gradient into gradient descent. Explains LLM alignment: supervised fine tuning then RLHF using a trained reward model made by removing the unembedding layer, and practical applications like A/B thumbnail testing and dynamic creative optimization.
AI-written summary · about
chapters (19)
- 0:00Reinforcement learning basics
- 1:06Simple decisions need better methods
- 3:13Neural training with backpropagation
- 5:19Backpropagation limitations
- 8:31RL for unknown outputs
- 10:20Policy gradients snack example
- 13:57Rewards in policy gradients
- 16:09Updating bias with gradient descent
- 17:56Improvement through repeated trials
- 20:46RL in business contexts
- 22:10LLMs trained with human feedback
- 24:41Pre-training vs alignment
- 26:12Fine-tuning for alignment
- 28:39RL to overcome overfitting
- 30:49Human feedback in RL with LLMs
- 32:17Building a reward model
- 34:24Final alignment of LLMs
- 35:26Marketing and sales applications
- 37:10Dynamic creative optimization
related talks
 49mReinforcement Learning: Demystifying the hype
 44mReinforcement learning: A gentle introduction
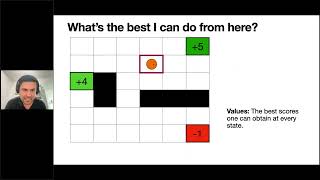 29mReinforcement Learning with Human Feedback
 01h 05mFoundations of RL
 47mReinforcement Learning via an Optimization Lens
 01h 11mFoundations of RL
 56mA Tutorial on Reinforcement Learning II
 14mHuman-in-the-Loop Reinforcement Learning