Reinforcement Learning via an Optimization Lens

summary
Argues that policy/value learning is a standard optimization problem solved via a primal–dual reformulation that replaces the non‑differentiable max and the double‑sample bias with a dual variable obtained by a Legendre transform, then further reduces the inner max by restricting the dual to an RKHS kernel loss L_k. Empirical results on Puddle World and MuJoCo show classical DP approximations diverging while the kernel loss yields stable decreasing Bellman error and value MSE, and variance‑reduction tricks give exponential speedups in convergence.
AI-written summary · about
chapters (21)
- 0:00Intro
- 2:24Reinforcement karning: Learning to make decisions
- 2:52Online vs. Offline (Batch) RL: A Basic View
- 4:40Outline
- 5:05Markov Decision Process (MDP)
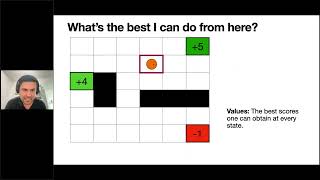
- 5:43MDP Example: Deterministic Shortest Path
- 7:08More General Case: Bellman Equation
- 8:14Bellman Operator
- 10:00When Bellman Meets Gauss: Approximate DP
- 11:22Divergence Example of Tsitsiklis & Van Roy (96)
- 12:58Does It Matter in Practice?
- 13:41A Long-standing Open Problem
- 15:00Linear Programming Reformulation
- 16:07Why Solving for Fixed Point Directly is Hard?
- 20:13Addressing Difficulty #2: Legendre-Fenchel Transformation
- 21:36Reformulation of Bellman Equation
- 28:29Primal-dual Problems are Hard to Solve
- 31:11A New Loss for Solving Bellman Equation
- 33:31Eigenfunction Interpretation
- 36:18Puddle World with Neural Networks
- 39:54Conclusions
related talks
 28mA Unifying View of Optimism in Episodic Reinforcement Learning
 34mOffline Reinforcement Learning and Model-Based Optimization
 09mLearning Under Requirements
 38mReinforcement Learning - What it is and How it Works
 45mPolicy Gradient: Optimal Estimation, Convergence, and Generalization beyond Cumulative Rewards
 01h 03mOverview of Statistical Learning Theory Part 2
 09mPrimal--Dual Optimization and Application to Sampling
 29mReinforcement Learning with Human Feedback