Deploying Data Science for Distribution of The New York Times
summary
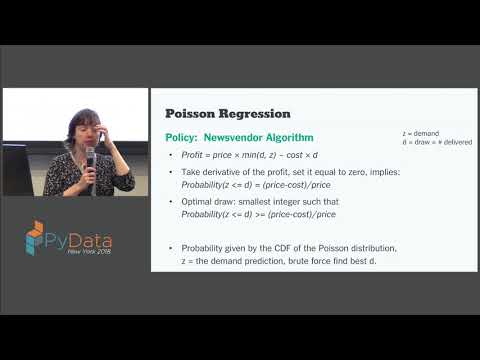
Built a deployed pipeline that replaces COBOL heuristics with Poisson regression with censoring-aware likelihood and an analytic newsvendor policy (augmented by a tunable Lagrange multiplier to trade profit for circulation), runs about 47,000 per-store, per-day models, and lives on Google Cloud Platform: App Engine (flex), BigQuery, Drone, Cloud Storage with weekly cron/task queues and Slack alerts. Experiments show higher profit vs BAU but some loss of sales, so stakeholders pick lambda values to restore circulation while keeping gains.
AI-written summary · about
chapters (14)
- 0:00Newspaper distribution challenge
- 1:25Legacy COBOL limitations
- 2:30Predictions and policy breakdown
- 3:39Autoregressive time series model
- 7:10Poisson regression for demand
- 12:10News vendor algorithm for deliveries
- 14:20Code refactor for scalability
- 15:03Experiment design with stores
- 18:40Profit versus sales optimization
- 23:17Algorithm comparison
- 24:03Google Cloud migration
- 26:53Data validation and Slack alerts
- 29:01Lessons from data science integration
- 30:28Q&A
related talks
 38mData science at The New York Times
 39mProductionising Data Science at Scale
 19mData science for real problems
 40mCausal machine learning for a smart paywall at The New York Times
 28mUse case in demand forecasting
 34mData Products, From 0 to data science pipeline
 31mFinding Needles in a Growing Haystack
 59mContinuous Intelligence: Keeping your AI Application in Production