The Lifecycle of Artificial Intelligence with IBM's Deep Learning as a Service
summary
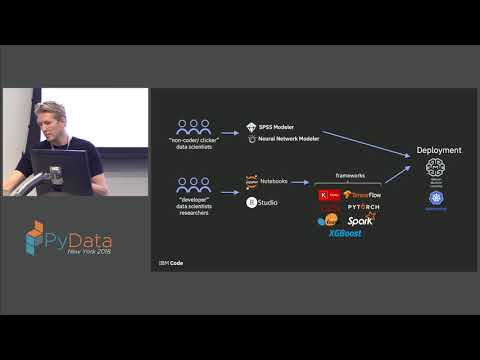
Claims a cloud service that trains evaluates and deploys models purely via API calls using fiddle (Fabric for Deep Learning) and Watson Studio, packages experiments as zip archives and stores data and logs in cloud object storage, runs distributed jobs across GPUs with random hyperparameter search and TensorBoard monitoring, and cites an IBM paper reporting 95% linear scale up to 256 GPUs; example Python SDK code submits and monitors parallel experiments and produces deployable model artifacts.
AI-written summary · about
chapters (11)
- 0:00Deep learning as a service intro
- 1:32Deep learning applications overview
- 7:13Training and deploying models
- 10:10Local DL environment challenges
- 13:01Introducing FfDL
- 15:55Watson Studio and IBM's AI IDE
- 19:09What is DL as a service
- 25:02Submitting DL tasks in Python
- 31:10Hyperparameter experiments
- 35:10Demo recap and code walkthrough
- 35:39Q&A on GPU scaling
related talks
 29mDeploy and Use a Multiframework Distributed Deep Learning Platform on...
 33mIBM's Approach to Building a Cloud-Native AI Platform
 09mUnlocking the value of your data
 27mAI at Scale in the Enterprise
 13mOperationalizing machine learning for the enterprise
 27mAI as a Service Scaling AI with Ease and Innovation
 35mJVM based DeepLearing on IoT data with Apache Spark
 10mTransforming AI into something real