LLMs and AI agents demystified
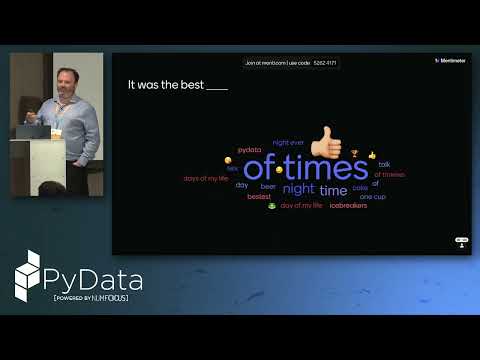
summary
Models primarily predict the next token using embeddings and transformer attention, scaled to hundreds of billions of parameters and trained on hundreds of billions to trillions of words with context windows into the hundreds of thousands. Fine‑tuning layers add chain-of-thought prompting for reasoning, supervised examples plus preference learning or direct preference optimization for chat quality, and verified rewards (run code/tests) to improve coding. Agents combine that LLM with a harness that does tool calling, local file access, git/GitHub operations, test runs, memory and sub‑agent decomposition.
AI-written summary · about
chapters (10)
- 0:00LLMs and AI agents intro
- 6:53How LLMs predict next word
- 10:05Attention and context in LLMs
- 13:55Transformers explained
- 17:48Fine-tuning LLMs for chat
- 20:13Reasoning and coding in LLMs
- 24:27LLMs to AI agents with tools
- 30:00LLM training pipeline
- 33:52Building autonomous agents
- 35:17Key takeaways
related talks
 01h 43mBuilding LLM Agents (Hackathon)
 02h 08mIntroduction to AI Agents
 41mBringing stories to life with AI, data streaming and generative agents
 41mBuilding LLM Agents – Challenges and Learnings
 50mIntelligent Agents, the New Frontier of LLMs
 37mExpanding the Capabilities of LLMs Through Community Collaboration
 01h 39mMastering LLMs: From Prompt Engineering to Agentic AI
 34mAI Agents: Transforming Autonomous Decision-Making