Txt2Vid: Ultra-Low Bitrate Compression of Talking-Head Videos via Text
summary
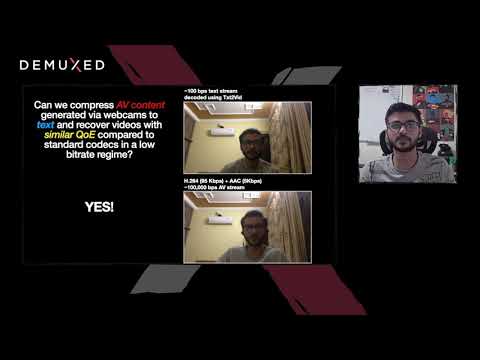
Claim: webcam talking‑head AV is compressed to text and reconstructed with similar QoE at 100–1000× compression (about ~100 bps) based on a subjective study (n=242). Pipeline uses voice cloning and TTS (Resemble.AI) plus lip‑sync (Wav2Lip), stores a short 30s driving video at decoder, and ships only text plus a user ID. A working streaming prototype demonstrates feasibility but shows high compute, latency, and cloud API dependence.
AI-written summary · about
chapters (7)
- 0:00Introduction to the problem
- 1:39Concept and goals
- 2:57Demo results
- 3:53The text-to-bit approach
- 5:16Performance evaluation
- 8:10Streaming demonstration
- 9:30Limitations and future work
related talks
 22mWhy TTS Models Now Look Like LLMs
 17mGemino: Practical and Robust Neural Compression for Video Conferencing
 21mCan AI Disrupt Speech Compression?
 09mBeyond Captions A Practical Pipeline for Live AI-Generated Sign Language Avatars
 20mRealtime Video AI with Diffusion Models
 27mWhat happens when AI starts grocking streaming audio directly
 05mRTC @Scale, Audio ML Session
 21mVeo 3 for Developers