Beyond BLEU & ROUGE — Evaluating LLMs and AI Systems

summary
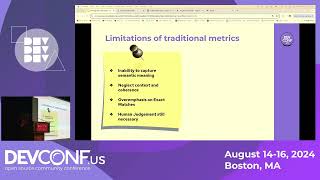
Claims that BLEU/ROUGE break on real dialogue (one-word correct answer “34” gets BLEU 0.016) and proposes concrete replacements: an fact score pipeline that breaks outputs into atomic facts and NLI-checks them, a BERT‑embedding BIRD metric for semantic match, a Langbite bias testing flow, and model‑graded evaluation (GVAL/GAL) that correlates best with humans. Examples include an OpenAI Eval run over 25 Spider samples yielding 20/25 correct (80%) and retriever stats like GPT‑3.5 ≈92% contextual position.
AI-written summary · about
chapters (23)
- 0:00Introduction and Session Overview
- 0:49Speaker Introductions
- 1:47Evaluating AI Systems: Beyond Traditional Metrics
- 2:28Key Dimensions of AI Evaluation
- 4:50Limitations of Traditional Metrics: BLEU and ROUGE
- 6:16Real-World Examples Highlighting Metric Flaws
- 10:17Understanding N-gram Overlap
- 13:12Modern Evaluation Frameworks
- 14:44Factual Accuracy and Fact Score
- 20:32Addressing Toxicity and Bias in AI
- 23:31Human-Centric Evaluation Methods
- 24:35Conclusion and Transition
- 25:38Introduction to Evaluation Shifts
- 25:50Strengths of Large Language Models in Evaluation
- 26:43Automated Evaluation: Importance and Benefits
- 27:24Key Technologies in Automated Evaluation
- 28:35Deep Dive: OpenAI Evolve Framework
- 32:40Generative Evaluation (GE) Explained
- 35:44Evaluation of Retrieval-Augmented Generation (REG) Systems
- 38:19Human Judgment vs. Automated Metrics
- 41:23Building Robust Evaluation Ecosystems
- 43:05Real-World Scenario: Evaluating Customer Service AI
- 45:22Conclusion and Future of Evaluation
related talks
 34mBuilding Trust with LLMs
 42mAdvancements in Evaluating Large Language Model Applications
 33mThe Silent Crash:Why Your RAG Evaluation Metrics Are Lying to You
 25mEngineering Better Evals: Scalable LLM Evaluation Pipelines That Work
 31mChallenges and Considerations in Language Model Evaluation
 24mHow to Keep Your LLM Chatbots Real - A Metrics Survival Guide
 27mThe Cutting Edge of AI: From LLMs to Multimodal Intelligence
 48mBeyond the Prompt: Evaluating, Testing, and Securing LLM Applications