Cloudflow: Spark, Flink, and Akka Working together on Kubernetes
summary
Cloudflow wires Spark, Flink, Akka and Kafka into Kubernetes with a Scala/Java API and an operator that compiles streamlet definitions into Docker images, provisions Kafka topics from the blueprint, and deploys via kubectl cloudflow deploy. Demo runs locally and on a cluster, showing a fraud‑detection pipeline that scores transactions with an ML model, uses Akka clustering and distributed data, and exposes a monitoring UI; build verifies types at compile time and automates scaling, packaging and undeploy.
AI-written summary · about
chapters (20)
- 0:00Introduction
- 1:04Why did we build Cloudflow
- 2:54Microservice best practices
- 4:48Apache Spark Flink
- 5:35Windowing and aggregation
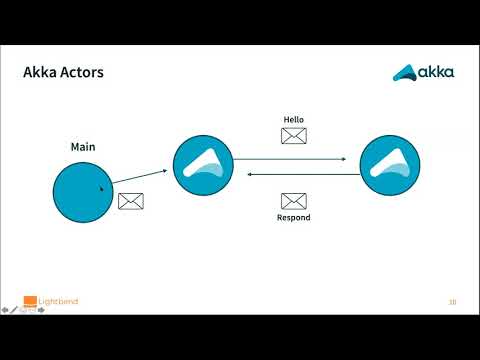
- 6:23Akka actors
- 8:03Akka streams
- 10:28Apache Kafka
- 10:58Cloudflow
- 12:56Cloudflow features
- 13:44Cloudflow API
- 14:04Engine Types
- 14:23Streamlets
- 15:25Blueprints
- 15:48Kafka Topics
- 16:45Cloudflow Monitoring
- 23:12Cloudflow Operator
- 23:39Cloudflow Deploy
- 24:22Cloudflow Scale
- 24:34Testing
related talks
 37mSpark and Flink Running Scalable in Kubernetes #bbuzz
 33mApache Kafka Devops with Kubernetes and Gitops
 35mBringing Your Data Pipeline into The Machine Learning Era
 14mKubeflow: Where ML Meets Kubernetes
 36mIntroducing Kubeflow (w. Special Guests Tensorflow and Apache Spark)
 31mIntroduction to Using and Use Cases of KubeFlow
 22mBuilding a Kubernetes Operator for Apache Flink in Java
 44mLets Deeploy Flink - Uncovering Hidden Depths of Yarn, Docker, Kubernetes & Beyond