Why you should stop pretending your sparse data is dense
summary
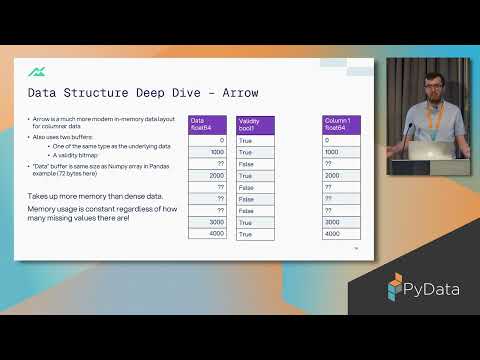
Compares concrete formats and measurements: pandas (NumPy-backed) uses NaN/NAT/None and promotes int to float, Arrow keeps the full data buffer plus an Arrow validity bit map (one bit per row), and ArcticDB (Man Group) stores only present values plus a bitset serialized with bit magic. Presents timings: single-column add ~57 ms in polars, aggregations ~30 ms, ArcticDB ~3× slower when dense but faster as density falls; shows where memory and CPU actually win or lose.
AI-written summary · about
chapters (13)
- 0:00Introduction
- 2:52Sparse data defined
- 8:52Pandas sparse limits
- 10:59Arrow’s missing values
- 15:32Polars sparse performance
- 16:13Arctic DB storage
- 19:45Bit Magic compression
- 22:12Arctic DB in-memory sparse
- 23:33Single column projection
- 24:13Two column projection
- 25:16Single column aggregation
- 26:17Pandas conversion plans
- 27:10Key takeaways and concluding remarks
related talks
 34mBridging Pandas and Polars
 32mThe PyArrow revolution in Pandas
 01h 22mAn Introduction to Pandas 2, Polars, and DuckDB
 26mSmall Big Data: using NumPy and Pandas when your data doesn't fit ...
 25mSpeed Up Data Access with PyArrow Apache Arrow Data is the new API
 28mArrow revolution in pandas and Dask
 01h 20mAdvanced Data Storage
 46mEfficient Data formats for Analytics with Parquet and Arrow